AI Readiness Assessment: A Practical Guide for Business Leaders
 Victoria Sokolova
.
Published
.
Digital Transformation
.
48 mins READ
Your organization may already pay for capable AI tools and still not be ready to use them in a real workflow. The gap is rarely the model. It is permission to use the data, a reviewer with time to check the output, a fallback for the day the system fails, or a clear definition of success. An AI readiness assessment finds those gaps before they become deployment problems.
This guide shows how to assess one use case across eight dimensions, record the evidence behind every answer, and build a transparent scorecard. You will see why a strong score cannot override a failed security or governance gate, and how to turn the result into a 90-day plan. Many leaders see the same pattern: AI is making everyone faster, and nothing is finishing sooner. For organizations whose projects share specialists, the guide shows why, and how to tell local time savings from capacity that moves delivery dates.
Key takeaways
- Assess one use case, not the whole company. Readiness depends on the scope, the data, the users, and the actions the AI may take.
- Score evidence, not intentions. A draft policy scores lower than a control that works.
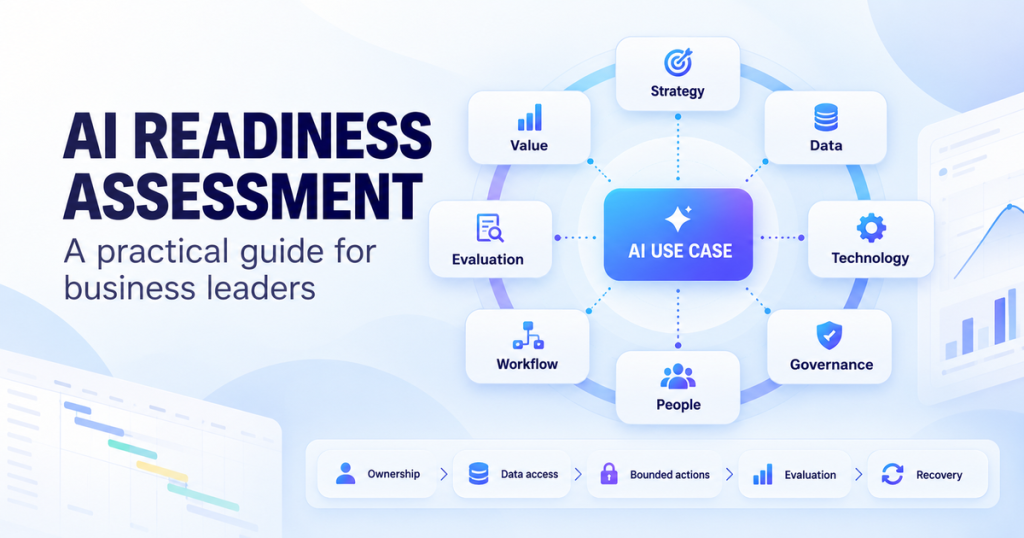
- Use eight dimensions: strategy, data, technology, governance, people, workflow, evaluation, and value.
- Let gates overrule the score. A failed check on data rights, permissions, approvals, evaluation, or fallback blocks the next stage, whatever the total.
- Count the hours that reach your bottleneck, the specialists every project waits for. Hours saved anywhere else rarely move a delivery date.
What Is an AI Readiness Assessment?
An AI readiness assessment is a structured, evidence-based review of whether an organization can introduce a specific AI use case responsibly and measure its business value. It examines strategy, data, technology, governance, people, workflows, evaluation, and economics, then turns gaps into a prioritized action plan.
The input is a defined scope: the use case, the business unit, the intended users, the data sources, the actions the AI may and may not take, and the harms that matter if it goes wrong. The output is a short pack: an evidence register, a scorecard, a list of blockers, a decision, and a plan with named owners.
Keep two depths apart. An initial self-check tells you where to look. A verification examines the artifacts themselves: the access test, the signed review, the evaluation results. A questionnaire can start an assessment. It cannot validate one.
AI readiness for business is therefore not a company-wide badge. It is an evidence-based decision about whether a specific AI use case can be introduced, operated, and measured within acceptable business and risk boundaries.
AI Readiness vs. AI Maturity, Data Readiness, and Compliance
AI readiness asks whether one use case can move to its next stage now. AI maturity describes how practices develop over time. Data readiness is one part of readiness. Compliance covers the obligations that apply. A readiness score never equals legal approval.
| Concept | The question it answers | Typical output |
| AI readiness | Can this use case move to its next stage now? | Scorecard, gates, decision, plan |
| AI maturity | How developed are our AI practices over time? | A level on an AI maturity model |
| AI data readiness | Is the data permitted, fit for purpose, and protected? | Data inventory, quality profile, access tests |
| Compliance | Which obligations apply, and can we show we meet them? | Scope-specific review and sign-off |
An AI maturity assessment suits a multi-year roadmap, not the question of whether next month's pilot may touch customer data. For the maturity of the project office itself, see our guide to PMO maturity models and assessment. In the EU, the AI Act sets duties for organizations that deploy AI systems, including AI literacy for their staff. Your legal team decides which duties apply. A score cannot.
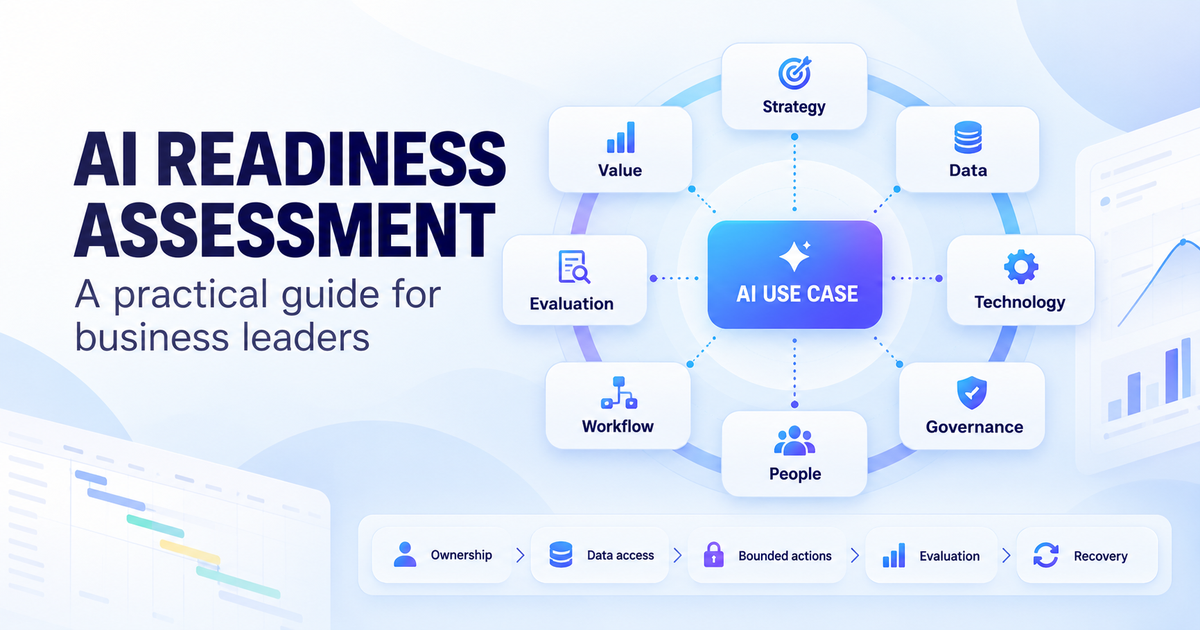
An Eight-Dimension AI Readiness Assessment Framework
A practical AI readiness assessment framework looks at eight dimensions of one use case. Most published AI readiness framework models use five or six pillars. The two added here, workflow and value, cover what happens after the technology works: who handles the exceptions, and whether the freed time changes anything.
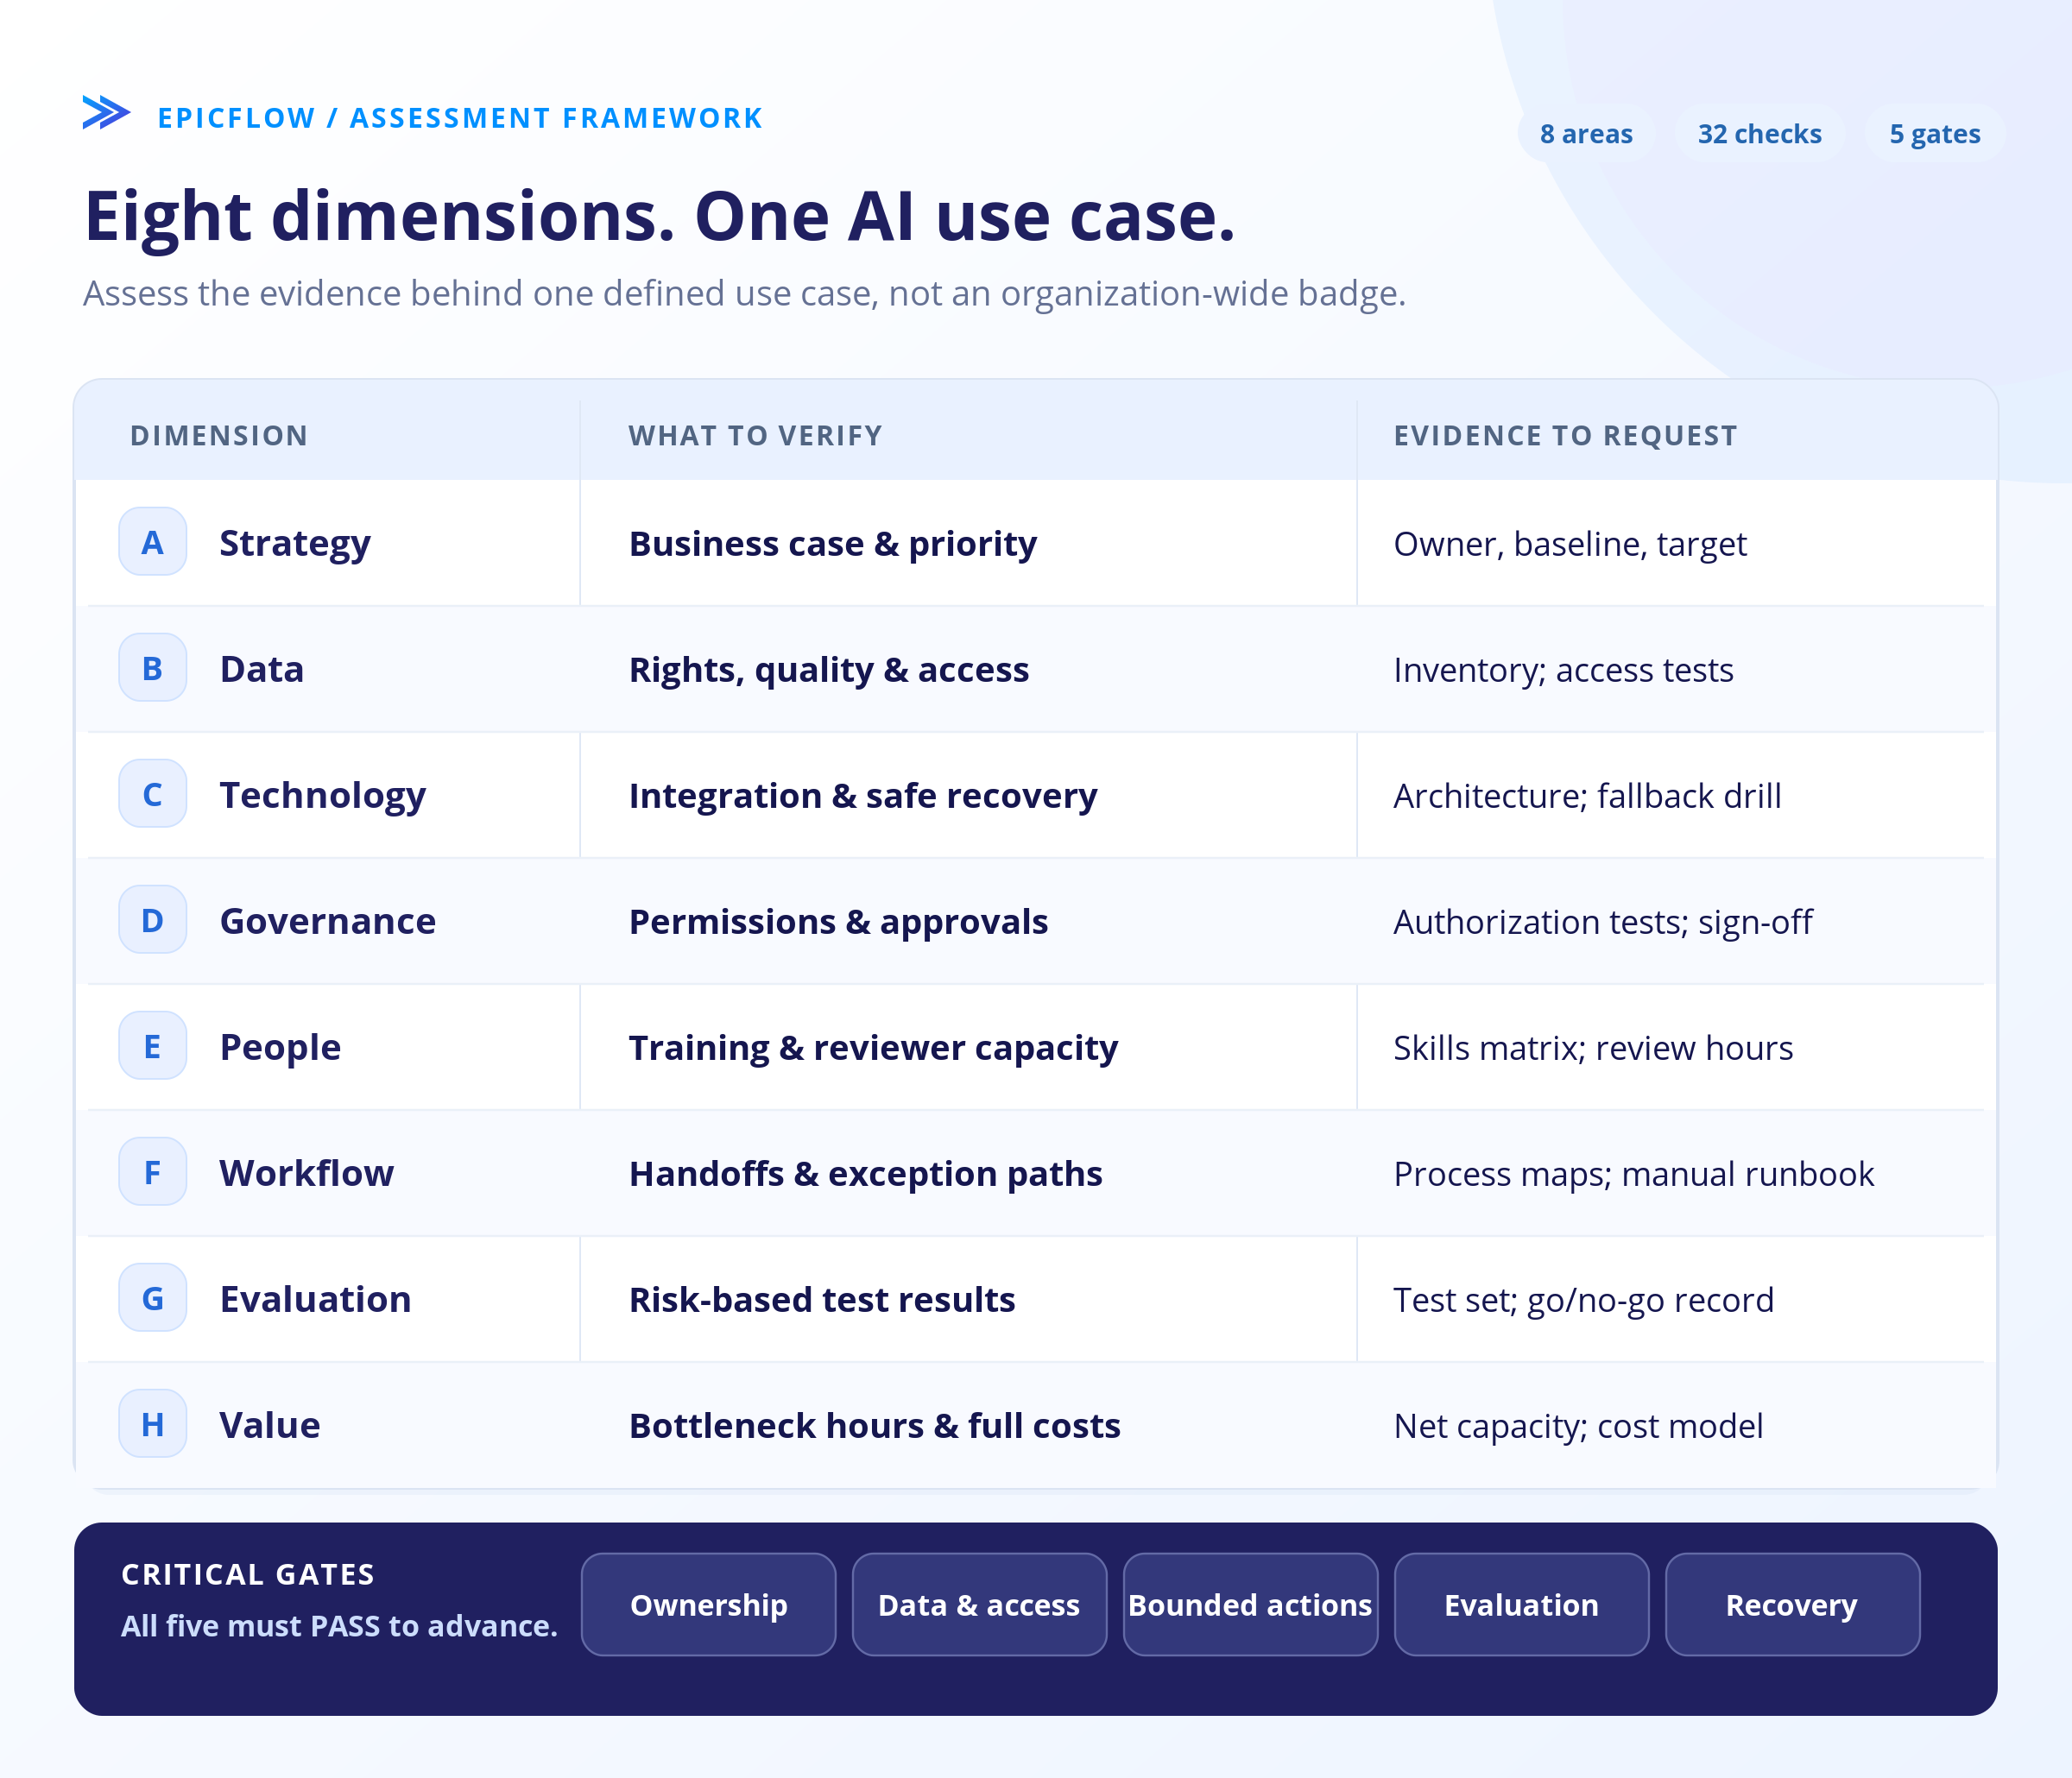
| Dimension | What you check | Typical red flag |
| A. Strategy and use-case prioritization | Owner, baseline, target, priority against other work | "Save time" is the only goal |
| B. Data readiness | Rights, quality, provenance, access, retention | Plenty of data, but nobody confirmed you may use it |
| C. Technology and integration | Architecture, environments, traceability, fallback | No tested way to switch it off |
| D. Governance, security, and risk | Permissions, approvals, legal review, incidents | The only control is an instruction in the prompt |
| E. People and change | Skills, training, reviewer capacity, user input | One expert is expected to check everything |
| F. Workflow and operating model | Handoffs, exceptions, support, manual fallback | Only the happy path is mapped |
| G. Evaluation and monitoring | Test cases, failure modes, monitoring, go/no-go | "It looked good in the demo" |
| H. Value, capacity, and economics | Full cost, net hours at the bottleneck, outcome, stop criteria | Hours saved are reported as money |
Strategy and Use-Case Prioritization
A named owner, a documented baseline, and a target measure turn "use AI" into a proposal you can test. Then rank the use case against everything else competing for the same people. Proof: the owner's mandate, the baseline, the portfolio shortlist.
Data Readiness
AI data readiness is about rights and fitness, not volume. You need permission to use the data for this purpose, data quality that fits the task, and retrieval that respects each user's access. Proof: the data inventory, a sample audit, negative access tests.
Technology and Integration
The architecture must meet the use case's needs for integration, availability, latency, and cost. A purchased assistant, a retrieval system, and an agent need different things; your own GPUs are rarely a prerequisite. Proof: an architecture diagram, run traces, a tested fallback.
Governance, Security, and Risk
Governance decides what the AI may touch and do. Permissions, approval for high-impact actions, and incident handling must be enforced outside the model and tested. Proof: authorization tests, a signed legal and security review, an incident runbook.
People and Change
Someone has to build, review, operate, and support the system. AI adoption readiness also depends on reviewer capacity, the item most assessments skip: if the only qualified checker is your busiest specialist, the AI adds load where you can least afford it.
Workflow and Operating Model
Map how work moves today and after the change, including handoffs, exceptions, and what happens when the AI is unavailable. Proof: as-is and to-be maps, exception routing tests, a manual runbook someone has actually run.
Evaluation and Monitoring
Define "good enough" before deployment and test against it, including wrong outputs, data leakage, prompt injection, and unauthorized actions. After release, monitor data quality, output quality, corrections, incidents, drift, and cost.
Value, Capacity, and Economics
Count every cost, including review and rework, then ask where the freed hours land. Speeding up work nobody was waiting for changes nothing. Delivery moves at the pace of the bottleneck, which in project organizations is a resource constraint: the specialists every project needs at the same time.
How This Framework Maps to NIST AI RMF
The NIST AI Risk Management Framework (AI RMF 1.0) organizes voluntary guidance into four functions: Govern, Map, Measure, and Manage. They are not maturity stages, and the NIST AI RMF Playbook says its suggested actions are not a checklist.
| Dimension | Related principle or source |
| A. Strategy | NIST Map: context and business purpose; Microsoft's business strategy driver |
| B. Data | NIST Map and Measure: data context; OWASP on leakage and injection |
| C. Technology | NIST Manage: operation and response; Cisco's infrastructure pillar |
| D. Governance | NIST Govern and Manage; OWASP Excessive Agency on permissions and approval |
| E. People | NIST Govern: roles and training; Cisco's talent and culture pillars |
| F. Workflow | NIST Map and Manage: use context, human-AI interaction |
| G. Evaluation | NIST Measure and Manage; OWASP adversarial failure modes |
| H. Value and capacity | Microsoft's business value framing; the capacity arithmetic is ours, not a NIST metric |
This is a conceptual crosswalk, not a certification mapping.
How to Conduct an AI Readiness Assessment in Six Steps
To assess AI readiness, define one use case, bring together a cross-functional team, collect evidence for 32 questions, score and challenge each answer, apply the critical gates, and agree a decision with owners. Time depends on how much evidence already exists. A workshop is a start, not an audit.
Step 1: Define the Use Case and Risk Boundary
First check whether the use case deserves an assessment at all. Three tests help, and the third is the one enthusiastic teams skip:
1. Is anything waiting on it? If this work runs late, does a finish date move? Most work fails here. If you don't know which team everything waits on, find your bottleneck first.
2. Does the wait cost real money? Some delays cost nothing. Others cost a contract penalty or a quarter's revenue.
3. Can a machine do it well? Well enough for a person to sign off, not merely quickly.
Pass one or two and you have found a saving. Pass all three and you have found a delivery result.
Then fill in a scope card: use case, business unit, users, model or service, data sources, allowed and prohibited actions, environment, material harms, owner, date, and methodology version. One scorecard covers one scope; if the scope changes materially, assess again.
Step 2: Assemble the Assessment Team
Invite the business owner, data owner, security, legal and privacy, the process owner, operations, finance, and the domain expert who will review the output. In project organizations, add the PMO lead or resource manager who knows where the bottleneck sits. Name one reviewer who does not own the initiative.
Step 3: Gather Evidence
For every question, collect the artifact, its date, and its owner. A documented absence is an answer; not knowing is a separate state, flagged UNKNOWN. Keep confidential artifacts in your own systems, never in public forms.
Step 4: Score and Challenge the Answers
Score each question from 0 to 4 on what operates today, not what is planned. Where a question has several parts, score the weakest proven part. Settle disagreements with artifacts, not votes.
Step 5: Apply Critical Readiness Gates
Check the five gates. Each returns PASS, FAIL, or UNKNOWN, and only PASS opens the next stage.
Step 6: Agree the Decision and Remediation Plan
Choose one of three outcomes: prepare and remediate, run a bounded pilot, or move to a deeper review before scaling. Record what may happen now, what may not, and what must be proven next.
AI Readiness Assessment Checklist: 32 Questions to Ask
This AI readiness checklist turns the eight dimensions into 32 questions. Use it as an AI readiness assessment questionnaire for one use case at a time, and record the evidence, its date, and its owner for every answer. A low score on a gate question blocks the next stage regardless of the total.
To use it as an AI readiness assessment template, copy the tables into a spreadsheet and add columns for score, UNKNOWN flag, evidence reference and date, owner, reviewer, gap, mitigation, due date, and gate state.
A. Strategy and Use-Case Prioritization
| ID | Question | What to check |
| A1 | Is there an accountable business owner and an executive sponsor for this specific AI use case? | Named owner, sponsor mandate, limits of responsibility. Gate question. |
| A2 | Are the intended business outcome, current baseline, and target measures documented? | Baseline, target, period, measurement method. "Save time" is not a target. |
| A3 | Has this use case been prioritized against competing initiatives, dependencies, and current delivery constraints? | Portfolio shortlist, dependencies, the suspected bottleneck, reason for the ranking. |
| A4 | Have you compared AI with simpler alternatives and defined what the solution must not do? | Decision record (rules, process change, or AI), scope exclusions, risk tier. |
B. Data Readiness
| ID | Question | What to check |
| B1 | Do you have the right to use the required data for this purpose, with named owners and approved sources? | Data inventory, owners, usage rights, license or contract scope. Gate question. |
| B2 | Is data quality, provenance, freshness, and version coverage adequate for the defined use case? | Quality profile, provenance, sample audit. Thresholds come from the task, not a generic 85% or 95%. |
| B3 | Are data access and retrieval tested to preserve each user's authorized scope? | Retrieval permission tests, negative access tests, no leakage between users. Gate question. |
| B4 | Are sensitive data, retention requirements, and external-provider data handling documented and controlled? | Classification, retention and deletion rules, processing terms, data-flow map. |
C. Technology and Integration
| ID | Question | What to check |
| C1 | Can the chosen architecture meet the use case's integration, availability, latency, and cost constraints? | Architecture diagram, workload assumptions, integration limits. |
| C2 | Are test environments, credentials, and configuration changes separated and managed securely? | Sandbox boundary, secrets process, version control, separation from production. |
| C3 | Can you trace each run to its model, prompt, retrieved sources, tool calls, and relevant configuration? | Run records with versions. Trace depth matches risk and privacy needs. |
| C4 | Has a shutdown, rollback, or safe manual fallback been tested for the intended workflow? | Drill record: recovery time, owner, preserved state. Gate question. |
D. Governance, Security, and Risk
| ID | Question | What to check |
| D1 | Are AI identities, tool permissions, and action boundaries enforced outside the model and tested for least privilege? | Named identity, action scope, authorization tests. A system prompt alone does not count. Gate question. |
| D2 | Have the applicable privacy, legal, security, and third-party requirements been reviewed and approved for this scope? | Scope-specific review and signed decision, not a general compliance badge. Gate question. |
| D3 | Are high-impact actions blocked until the required human approval is verified and enforced? | Approval policy and bypass tests. For a read-only scope, proof that write actions are blocked. Gate question. |
| D4 | Are incident escalation, accountability, and proportionate audit records defined and usable? | Incident runbook, escalation contacts, sample audit trail, drills. |
E. People and Change
| ID | Question | What to check |
| E1 | Are the skills and responsibilities needed to build, review, operate, and support this use case covered? | Skills matrix with real availability, not only a hiring plan. |
| E2 | Have users been trained on approved use, limitations, escalation, and appropriate reliance on AI outputs? | Task-specific training, awareness checks, usage policy. |
| E3 | Do qualified reviewers have sufficient time, authority, and expertise to handle expected output and exceptions? | Reviewer capacity model per role: workload, queue, escalation authority. |
| E4 | Have affected teams contributed to workflow design and received a way to report errors and adoption barriers? | Workshop record, feedback route, named issue owner. |
F. Workflow and Operating Model
| ID | Question | What to check |
| F1 | Are the current and proposed workflows mapped, including handoffs and control points? | As-is and to-be maps, process boundaries, inputs and outputs. |
| F2 | Are exception paths, out-of-scope cases, and human escalation rules documented and tested? | Exception categories and routing tests, not only the happy path. |
| F3 | Are service ownership, support expectations, and downstream capacity agreed? | Support owner, expected volume, service levels, downstream load. |
| F4 | Can the organization continue the process safely if the AI system is unavailable or its output is rejected? | Manual runbook, available staff, retrievable state. |
G. Evaluation and Monitoring
| ID | Question | What to check |
| G1 | Do representative test cases and risk-based acceptance criteria exist before deployment? | Evaluation set, baseline, quality and safety criteria, accountable approver. Gate question. |
| G2 | Have you tested relevant failure modes, including incorrect outputs, data leakage, prompt injection, and unauthorized actions? | Adversarial and negative test results with remediation. |
| G3 | Are output quality, human corrections, incidents, drift, and usage costs monitored against defined limits? | Monitoring in place, alert owners, sampling rules, cost limits. |
| G4 | Is there documented evidence that the proposed release meets its acceptance criteria, with an accountable go/no-go decision? | Release record, known limitations, approved risk acceptance. Gate question. |
H. Value, Capacity, and Economics
| ID | Question | What to check |
| H1 | Does the business case include setup, operation, review, rework, and ongoing change costs? | Cost per period: integration, licenses or usage fees, review, exceptions, support, evaluation. |
| H2 | Are net usable hours calculated for the bottleneck role after adoption, review, and rework? | Task-level model: adoption rate, skill, reviewer load. Hours from different roles are not added up. |
| H3 | Can the released capacity affect delivery, output, or a measurable business outcome rather than only local task speed? | Bottleneck and dependency scenario, demand for the freed hours. Hypothesis and observed result kept apart. |
| H4 | Are success, stop, and scale criteria agreed, with an attribution approach and a reassessment date? | Decision thresholds, baseline, reassessment triggers, named stop owner. |
How to Calculate and Interpret Your AI Readiness Score
Score each of the 32 questions from 0 to 4, add the scores, and divide by 128 to get an AI readiness score from 0 to 100. Report unknowns and evidence coverage next to it, then apply the gates. The score summarizes; the gates decide.
About this scorecard. This scorecard is an editorial decision-support framework, not a validated benchmark, certification, legal opinion, or prediction of AI success. Its thresholds and equal weights are working assumptions. Apply risk-specific controls and independent review where appropriate; a high score never overrides a failed critical gate.
Use a 0 to 4 Evidence Rubric
| Score | What the evidence shows |
| 0 | Not in place, or no evidence. If the state is unknown, also flag UNKNOWN. |
| 1 | An agreed plan and a named owner, but nothing operates yet in this scope. A draft policy is a 1. |
| 2 | Implemented and demonstrated in a limited test or pilot, with scope, date, and exceptions recorded. |
| 3 | Verified repeatedly on representative cases, with results reviewed and accountability clear. |
| 4 | Operating reliably in production for this scope, monitored and reviewed. |
Calculate the Score Without Hiding Unknowns
Each dimension has four questions and an equal weight of 12.5%, a simple assumption for reproducibility, not a claim that all risks are equal.
- Dimension mean d = (q1 + q2 + q3 + q4) / 4, and dimension percentage = 25 × d.
- Composite S = 100 × (sum of all 32 scores) / 128, rounded only for display.
An UNKNOWN counts as 0 in a provisional, lower-bound score, and its flag stays visible. Evidence coverage is the share of the 32 questions with a documented state. If any answer is UNKNOWN, report the provisional score, the coverage, and the unknown IDs as "insufficient evidence", not as a band. Never drop unknowns from the denominator.
There is no N/A option: for a read-only use case, D3 scores the proven block on write actions. Do not average use cases into one company score, and do not change weights after scoring.
Apply Gates Before Making a Decision
| Composite score | Working label | How to read it |
| Below 25 | Foundation gaps | Basic prerequisites and evidence are missing. |
| 25 to under 50 | Preparation in progress | Close material gaps; test a limited scope. |
| 50 to under 75 | Scoped-pilot review candidate | A pilot decision is possible only if every gate passes and the risk owner approves. |
| 75 to 100 | Scale-review candidate | Eligible for a deeper scale review. Not certification, not automatic approval. |
A band appears only at 100% coverage, always next to the gate results. Any dimension mean below 2 is a material gap, whatever the composite. These bands and the threshold of 2 are assumptions of this template, not official NIST, Cisco, or Microsoft levels.
| Gate | Questions | If FAIL or UNKNOWN |
| Accountable ownership | A1 | Assign an owner before the AI takes any real action. |
| Permitted data and access | B1, B3, D2 | No protected or unapproved data; only an approved sandbox with synthetic or public data. |
| Bounded actions and approval | D1, D3 | No live write or high-impact actions. A prompt instruction does not replace a control. |
| Evaluation and release evidence | G1, G4 | Offline evaluation only. |
| Safe operation and recovery | C4 | Do not connect a production workflow. |
A gate passes when every listed question scores at least 2 with verified evidence for the stage you want to enter. UNKNOWN means no transition. The gates are a minimum, not a security audit, and approval for one stage covers that stage only.
Worked Example: Is an AI-Assisted Engineering Review Ready for a Pilot?
Here is the scorecard applied to one hypothetical workflow. It scores 56.25 out of 100, inside the pilot-review band, and still fails three gates. The right decision is to fix the blockers before any pilot touches live data or takes live actions.
All numbers here are hypothetical, not a client case. An engineering organization wants AI to triage design review requests and draft review notes. The AI will not approve engineering decisions, certificates, safety acceptance, or production changes. Scope: one review workflow, one expert group. Coverage is 100%; D3 is a known 0, because the approval control does not exist.
Read the Score and the Blocker
| Dimension | Question scores | Mean | Dimension % |
| A. Strategy | 3, 3, 4, 2 | 3.00 | 75% |
| B. Data | 2, 3, 1, 2 | 2.00 | 50% |
| C. Technology | 3, 4, 3, 2 | 3.00 | 75% |
| D. Governance | 1, 2, 0, 1 | 1.00 | 25% |
| E. People | 2, 3, 2, 1 | 2.00 | 50% |
| F. Workflow | 2, 1, 3, 2 | 2.00 | 50% |
| G. Evaluation | 2, 2, 3, 1 | 2.00 | 50% |
| H. Value | 3, 3, 4, 2 | 3.00 | 75% |
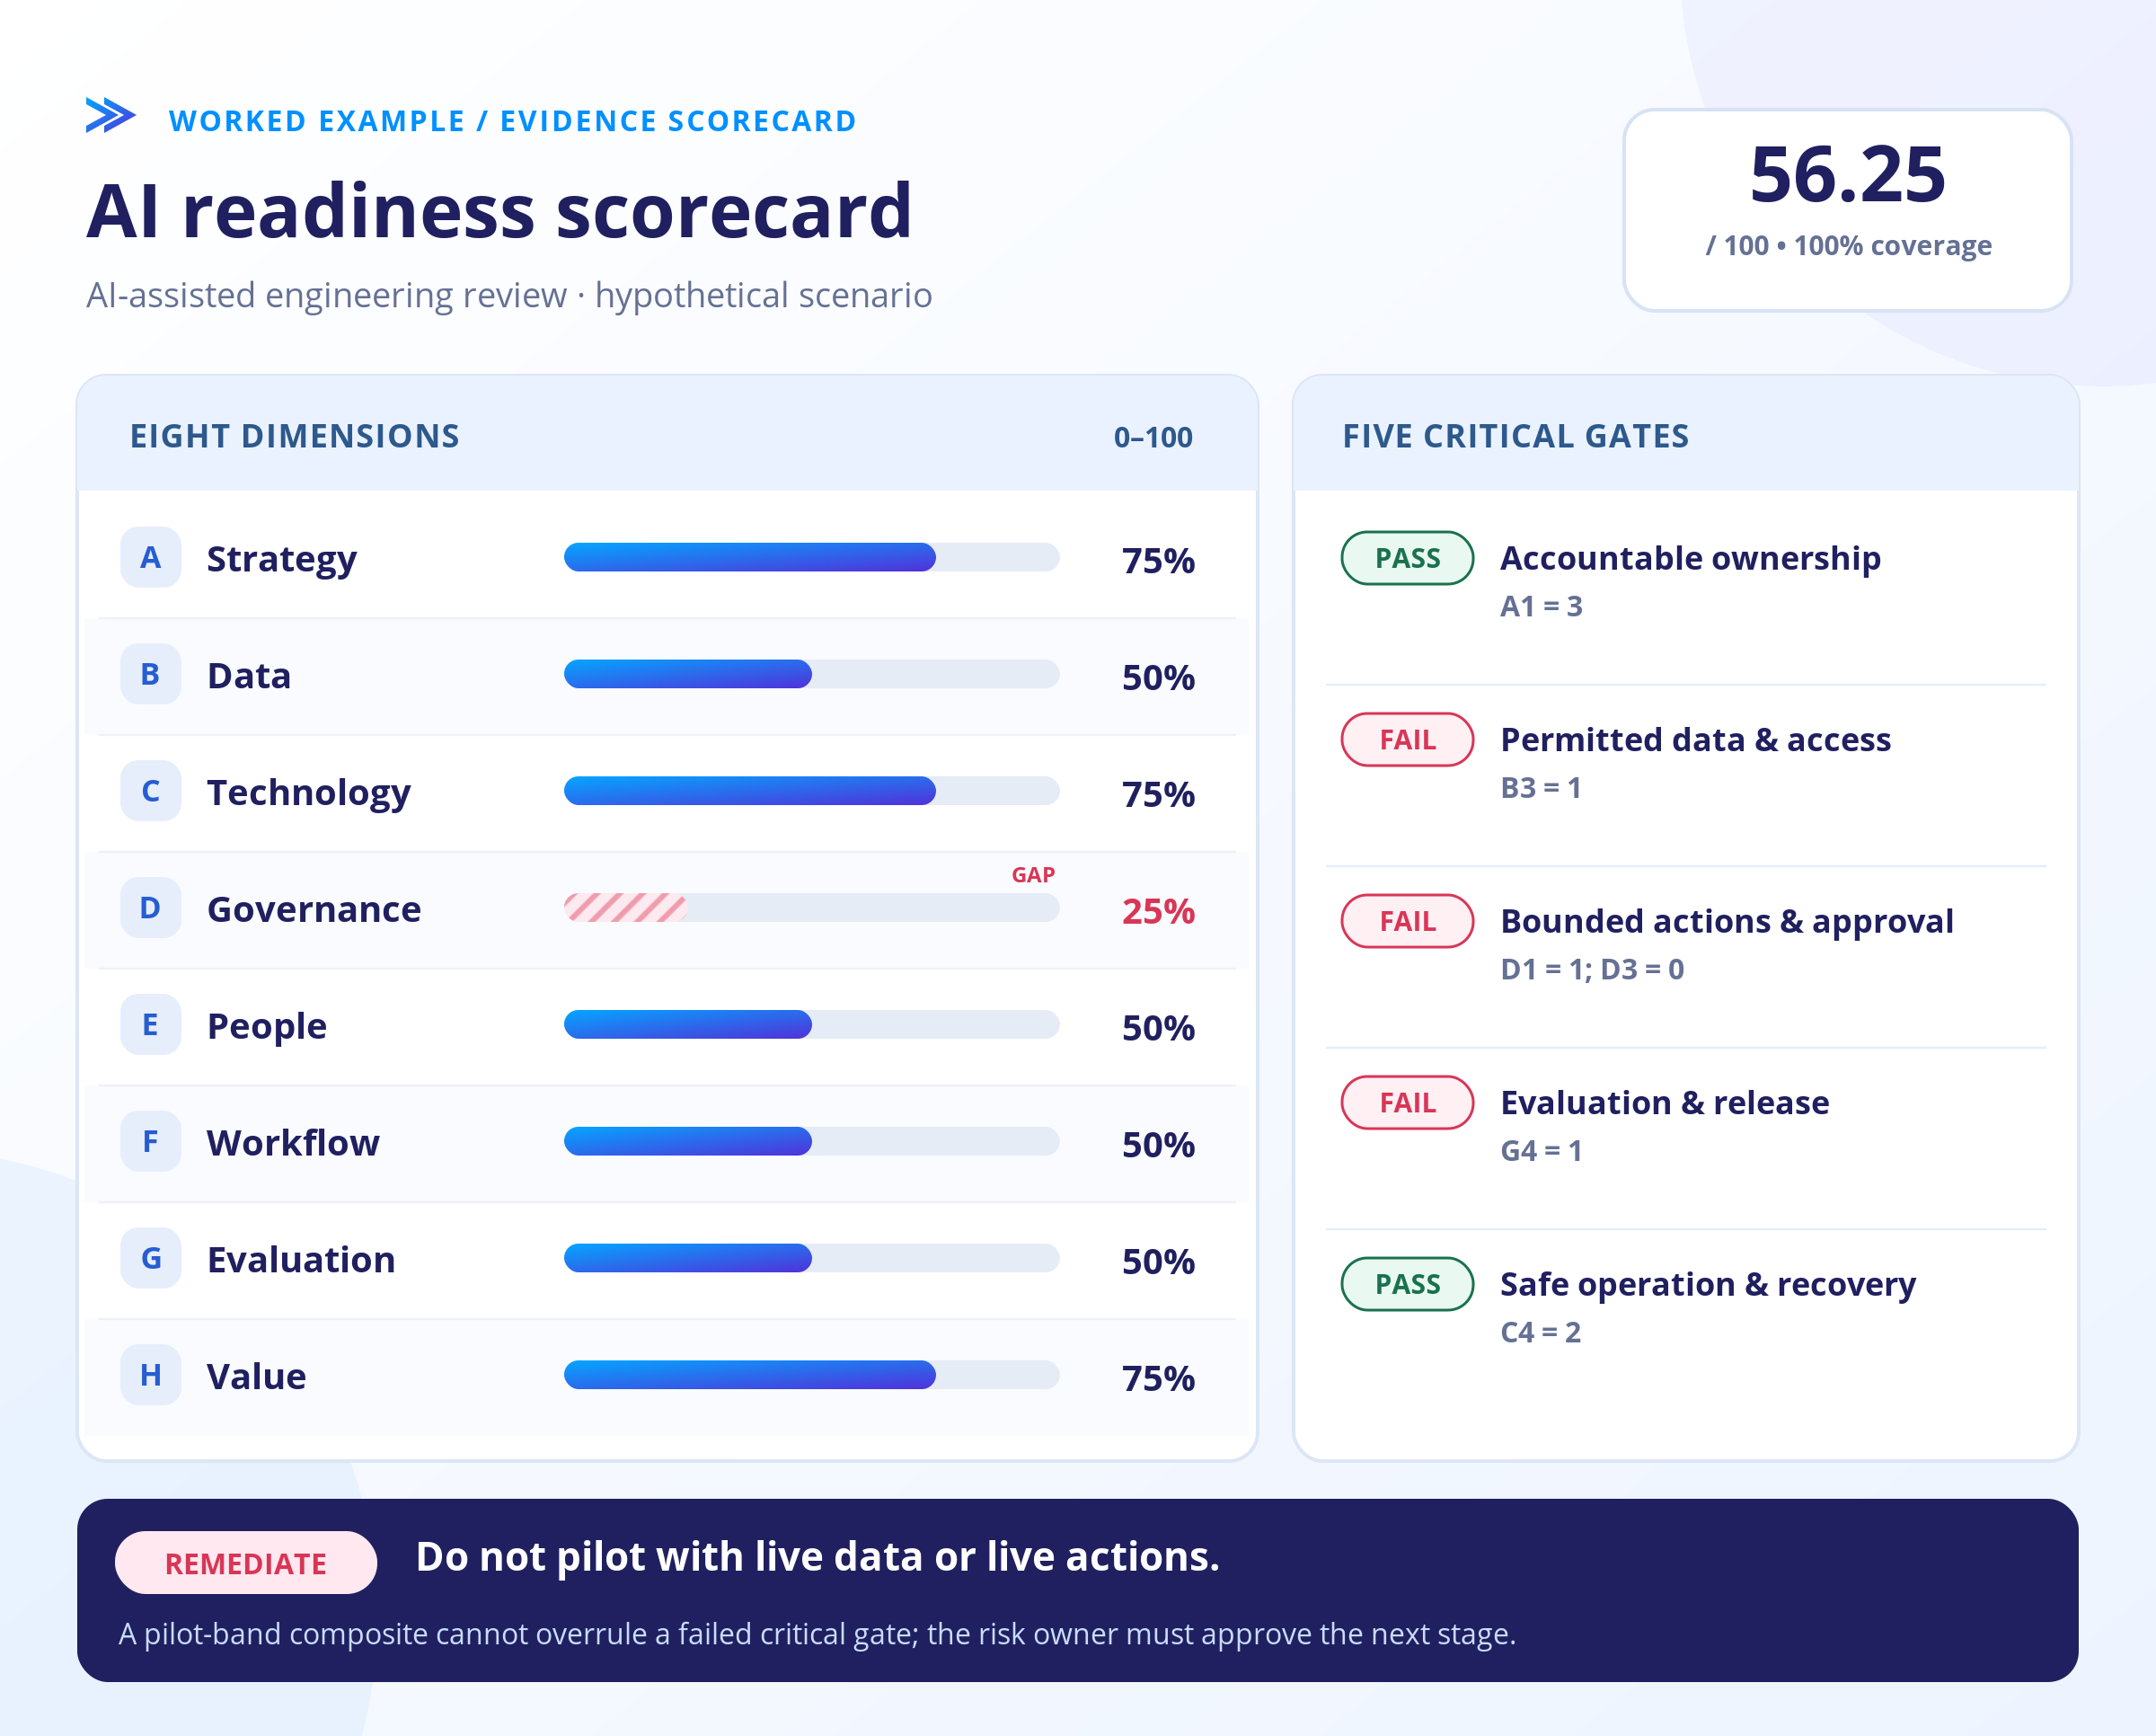
Figure 2. A pilot-band score with three failed gates. The gates decide.
The 32 scores add up to 72 out of 128, so S = 100 × 72 / 128 = 56.25. On the bands alone, this is a scoped-pilot review candidate. The gates say otherwise:
- Permitted data and access: FAIL. B3 = 1: retrieval is untested against each user's access rights.
- Bounded actions and approval: FAIL. D1 = 1, D3 = 0: permissions are not enforced outside the model, and no approval control exists.
- Evaluation and release evidence: FAIL. G4 = 1: no documented go/no-go.
- Ownership (A1 = 3) and recovery (C4 = 2): PASS.
Governance also averages 1, a material dimension gap. Decision: remediate before any pilot with live data or live actions. An isolated synthetic-data test is the risk owner's call; the score grants no permission. And 56.25 does not mean "56% ready", nor a probability of success.
Calculate Net Specialist Capacity
Now assume the blockers are fixed and a pilot is approved. How much time does the AI give back to the specialist the projects wait on? Treat this as a planning hypothesis.
Assumptions: one bottleneck role, a senior review engineer. 100 similar tasks a month at 1 hour each. AI is used on 80% of them. Every AI draft gets a 15-minute human review, and one in five needs 30 minutes of extra rework. Oversight takes 5 hours a month.
| Item | Calculation | Hours per month |
| Current workload | 100 × 1 h | 100 |
| Tasks done with AI | 100 × 0.80 | 80 tasks |
| Review of AI drafts | 80 × 0.25 h | 20 |
| Extra rework | 80 × 20% × 0.5 h | 8 |
| Ongoing oversight | Assumption | 5 |
| Remaining manual tasks | 20 × 1 h | 20 |
| New workload | 20 + 8 + 5 + 20 | 53 |
| Net hours released | 100 − 53 | 47 |
The formula for identical tasks and one role:
H_net = N × a × (t_manual − t_review − r × t_rework) − H_oversight
N is eligible tasks, a the share done with AI, r the share needing rework. Here: 100 × 0.8 × (1 − 0.25 − 0.2 × 0.5) − 5 = 47 hours a month. If review time already includes rework, do not subtract it twice.
Forty-seven hours is an upper estimate for this one role. It is not 47 hours of anyone's time, and it is not a cash saving.
Review time drives the result. At 45 minutes per draft, the net release falls to 7 hours a month. At 54 minutes, it turns negative: minus 5 hours. Our page on AI agents as a resource shows the same effect: when the bottleneck specialist prepares and checks an agent's work, around three quarters of the task time can stay on the bottleneck. Hence a design rule. Whoever prepares and checks the AI's work should not be your bottleneck. That works where someone else can judge the result because a standard exists. Where only the expert can judge it, start somewhere else.
Before counting these hours as a portfolio benefit, check that they fall in the weeks the projects need them, that queued work exists for the specialist, and that review has not moved the queue downstream (AI capacity planning covers that side). For ROI, count every incremental cost, and publish no figure until benefits are observed. Multiplying 47 hours by a rate is not profit.
Turn Readiness Gaps into a 90-Day Action Plan
Turn every gap into an action with an owner, a dependency, a due date, and the evidence that will close it. Sequence the work in three 30-day horizons, each gated by the one before. Ninety days is a planning template, not a promise of readiness.
| Horizon | Actions | Exit condition |
| Days 0 to 30: set the boundaries | Confirm scope and data, assign owners, settle permissions and approvals, define acceptance criteria and test cases | Every condition for the permitted environment verified; no gate UNKNOWN |
| Days 31 to 60: test a bounded pilot | After sign-off only: limited volume, human review, exception and adversarial tests, a shutdown drill; measure review time and cost | Acceptance criteria met, incidents reviewed, real review and rework figures known |
| Days 61 to 90: decide to scale or stop | Compare with the baseline, check the bottleneck and downstream effects | A proven outcome and approval for the next stage; otherwise remediate or stop |
Fix legal, security, and safety blockers first, then the gaps that stop the chosen outcome, then improvements by effort and impact. Write each action as one row: gap ID, change, owner, dependency, estimate, due date, acceptance evidence, verifier. That makes the plan the first 90 days of an AI implementation roadmap for this use case, built from evidence rather than ambition. Its executive summary answers three questions: what can we do now, what can we not do, and what must we prove next?
What Changes for Generative AI and AI Agents?
A generative AI readiness assessment uses the same eight dimensions, but the risks move. The more an AI system can do on its own, the more evidence you need on permissions, approvals, traceability, and cost. More autonomy does not mean more readiness.
| Type | What it does | Where readiness evidence matters most |
| Predictive AI | Scores, classifies, or forecasts | Data quality, drift, evaluation against a baseline |
| Generative AI for drafting | Produces text, code, or summaries a person uses | Data leakage, unreliable output, reviewer time |
| AI agents | Takes actions through tools and systems | Identity, least privilege, human approval, run traces, cost limits |
Two OWASP entries map onto the questionnaire. Prompt injection (LLM01) describes instructions hidden in user input or retrieved content that redirect a model; test for it under G2 and keep retrieval permission-aware under B3. Excessive agency (LLM06) covers agents with more functionality, permissions, or autonomy than the task needs; its remedies, including minimal permissions and human approval for high-impact actions, are what D1 and D3 check. NIST's Generative AI Profile (NIST AI 600-1) applies the AI RMF to generative AI risks.
One effect is easy to miss. An agent does not tire, but the person who checks its work does. If that person is already your bottleneck, a well-governed agent can still slow delivery. Plan the checking as work, with a name and hours. Our article on AI agents for project management covers agent roles and examples.
Common AI Readiness Assessment Mistakes
Most assessment errors make a use case look more ready than it is. Check for these seven.
1. Assessing the company in the abstract. "Are we AI-ready?" has no answer. "Is this workflow ready for a bounded pilot?" does.
2. Scoring plans as if they were in place. A purchase order or a draft policy is a 1, not a 3.
3. Changing the rubric to improve the result. Weights and thresholds are fixed before scoring starts.
4. Averaging away a blocker. A missing approval control stays a blocker at any composite score.
5. Confusing data volume with fitness. More records do not fix missing rights or broken access rules.
6. Ignoring the reviewer bottleneck. If only one expert can check the output, that expert's calendar is your capacity limit.
7. Calling hours money, or a score compliance. Freed hours stay a hypothesis until redeployed, and a score is not a legal opinion.
Self-Assessment, Assessment Tool, or Independent Review?
Pick the format by the decision you need to make. A quick self-check starts the conversation. A vendor's AI readiness assessment tool gives a directional diagnosis. A cross-functional evidence review supports a pilot decision. Specialist review is needed where the risk calls for it.
| Format | Best for | Limits |
| Quick self-check, such as Microsoft's AI Readiness Wizard (ten questions across five drivers, from business strategy to governance and security) or the OECD's pilot tool for small and medium-sized firms | Discovery and a first executive conversation | Self-reported answers, no evidence check |
| Vendor assessment tool, such as Cisco's AI Readiness Assessment (strategy, infrastructure, data, governance, talent, culture) | Orientation against a vendor's framework | Scoring logic often not fully visible; scores do not compare across tools |
| Cross-functional evidence review (this guide) | A pilot decision for one use case | Needs owners' time and an independent reviewer |
| Independent or specialist review | Regulated, safety-critical, or high-impact scopes | Needed in addition to the above, not instead |
Tool descriptions reflect each publisher's public page as of October 2026. The "best for" labels are our editorial judgment.
Does Company Size Change the Assessment?
The questions stay the same; the people answering them change. In a small or medium-sized business, one person may own data, security, and operations, so independent review is harder to arrange and credentials are often shared too widely. Give C2 and D1 extra attention. In enterprise AI readiness work, the challenge runs the other way: many evidence owners and a long route to a signed decision. A country-level index, such as UNESCO's readiness methodology for national governments, answers a different question.
From AI Readiness to Portfolio-Level Delivery Value
Readiness tells you whether a use case can run safely, not whether it will change what your portfolio delivers. That depends on where the freed hours land.
When many projects share specialists, delivery moves at the pace of the bottleneck. An hour freed there is an hour more output for the whole portfolio; an hour freed anywhere else changes little. So count the bottleneck hours an AI resource gives back, not the hours it works.
Free 10% of your bottleneck's time, with first-pass reviews for example, and you can deliver up to 10% more with the same people. Because they are already paid for, profit moves faster than output: at a 10% net margin, with materials at 40% of revenue, 10% more output means up to 60% more profit. That holds only if the freed hours sit at the bottleneck and work is waiting for them, which is why H2 and H3 are in the questionnaire.
Epicflow plans an AI agent like any other resource, with capacity, a rate, and dates, and shows where it earns the most. The agent runs on the platform you already use, or on EpicStaff, the governed operating layer for AI agents, included with Epicflow. A person signs off its output. At the Dutch Ministry of Defence, our agents run on the ministry's own language model, DefGPT; one sets up new procurement projects in Epicflow from a template. Every week that work waits at the bottleneck has a price, its cost of delay, and the forecast shows which agent changed delivery and which only saved hours. See how agents work as a resource.
Conclusion: Choose the Next Safe, Measurable Step
The result of an AI readiness assessment is not a number. It is a decision and a named owner for the next step: what you may do now, what you may not, and what you must prove first. Work through the AI readiness checklist above, let the gates decide, and measure value where your projects actually wait.
Planning an AI pilot across shared project teams? Send us your project list. We build a model of your own portfolio and show you, in one session, where your bottleneck is and what an hour freed there is worth, before you count local time savings as a portfolio benefit.
Discuss your portfolio capacity scenario
AI Readiness Assessment FAQ
What is an AI readiness assessment?
It is a scope-specific review of whether your organization can introduce one AI use case safely and measure its value. It checks evidence across strategy, data, technology, governance, people, workflow, evaluation, and economics, names the gaps and their owners, and ends in a decision: prepare, pilot, or review before scaling.
How do you measure AI readiness?
Measure it per use case, across several dimensions, against an evidence rubric. In this guide each of 32 questions scores 0 to 4, and the total becomes a composite from 0 to 100. The composite is only a summary: critical gates decide what happens next, and no universal benchmark exists.
What are the five stages of AI readiness?
There is no single standard five-stage model. Tools use different numbers of levels and measure different things. Keep three ideas apart: dimensions (what you assess), answer levels (how you score each question), and stages (how practice develops over time). If you cite a five-stage model, name its source.
How long does an AI readiness assessment take?
It depends on the depth. A quick self-check takes minutes and gives a direction. An evidence review for one use case takes as long as the owners need to produce the artifacts. A specialist security or legal audit takes longer still. Scope, risk, and the evidence you already hold set the timeline.
Can a company run an AI readiness assessment without a consultant?
Yes, for an initial self-assessment, if the review is cross-functional and someone independent of the initiative challenges the scores. It does not replace security, legal, privacy, or safety expertise where the scope requires it, and high-risk or regulated use cases still need specialist review.
Does a high AI readiness score mean we can deploy AI agents autonomously?
No. A high score cannot override a failed gate. Agents still need enforced permissions, bounded actions, evaluation, human approval for high-impact steps, a risk decision, and monitoring. Review capacity is finite too: an agent whose output lands on your busiest specialist can slow delivery even when every control works.
Methodology and Sources
Methodology note. The scorecard in this guide (version 1.0, October 2026) is an editorial synthesis by Epicflow: 8 dimensions, 32 questions, a 0 to 4 evidence rubric, equal weights, an explicit rule for unknown answers, and five critical gates. It has not been empirically validated, and it is not a NIST, Microsoft, Cisco, or industry standard.
Sources
- NIST, AI Risk Management Framework (AI RMF 1.0)
- NIST, AI RMF Playbook
- NIST, Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile (NIST AI 600-1)
- Microsoft, AI Readiness Wizard
- Cisco, AI Readiness Assessment
- OECD, AI readiness tool for SMEs (pilot)
- OWASP GenAI Security Project, LLM01: Prompt Injection
- OWASP GenAI Security Project, LLM06: Excessive Agency